Writing
Statistics tutorials for people who run evals, notes on things I’ve built, and the occasional essay.
series
// read in orderJudging the Judges
Agreement and calibration statistics for LLM judges and human annotators – what survives once chance gets its share.
Error Bars for Evals
How sure you are about a benchmark score, and where the next thousand samples should go: uncertainty and experiment design for LLM evals.
all posts
// 12, newest first2026
Python Gym: Practicing the Part the Agents Do Now
Agents write most of my Python now, and my own fluency had slipped. Reading and judging code was fine; writing it from a blank file was slower than it used to be.
Attractors: Finding Order Inside Chaos
An instrument for finding and drawing strange attractors: 51 chaotic systems rendered live on the GPU, a search that hunts for new ones, and an editor for your own equations.
Correlation Is Not Calibration
You want an LLM judge to replace your human graders, so you run the validation study everyone runs: 200 responses, each scored 1–10 by a human expert and by the judge.
Clustered Data and the Sampling Budget
Your agent eval grades 100 conversations, 10 turns each: 1,000 graded rows. The pass rate comes in at 70%, and the naive 95% confidence interval is
Paired Deltas: Compare Models on the Questions They Share
Model A scores 390/500 on your benchmark: 78%. Model B scores 400/500: 80%. A two-point gap, and everyone is ready to promote checkpoint B.
Your Benchmark Score Has Error Bars
Your model scores 78.0% on your team’s 500-question benchmark. A new checkpoint comes back at 79.2%. Merge it?
Prime Spiral Explorer
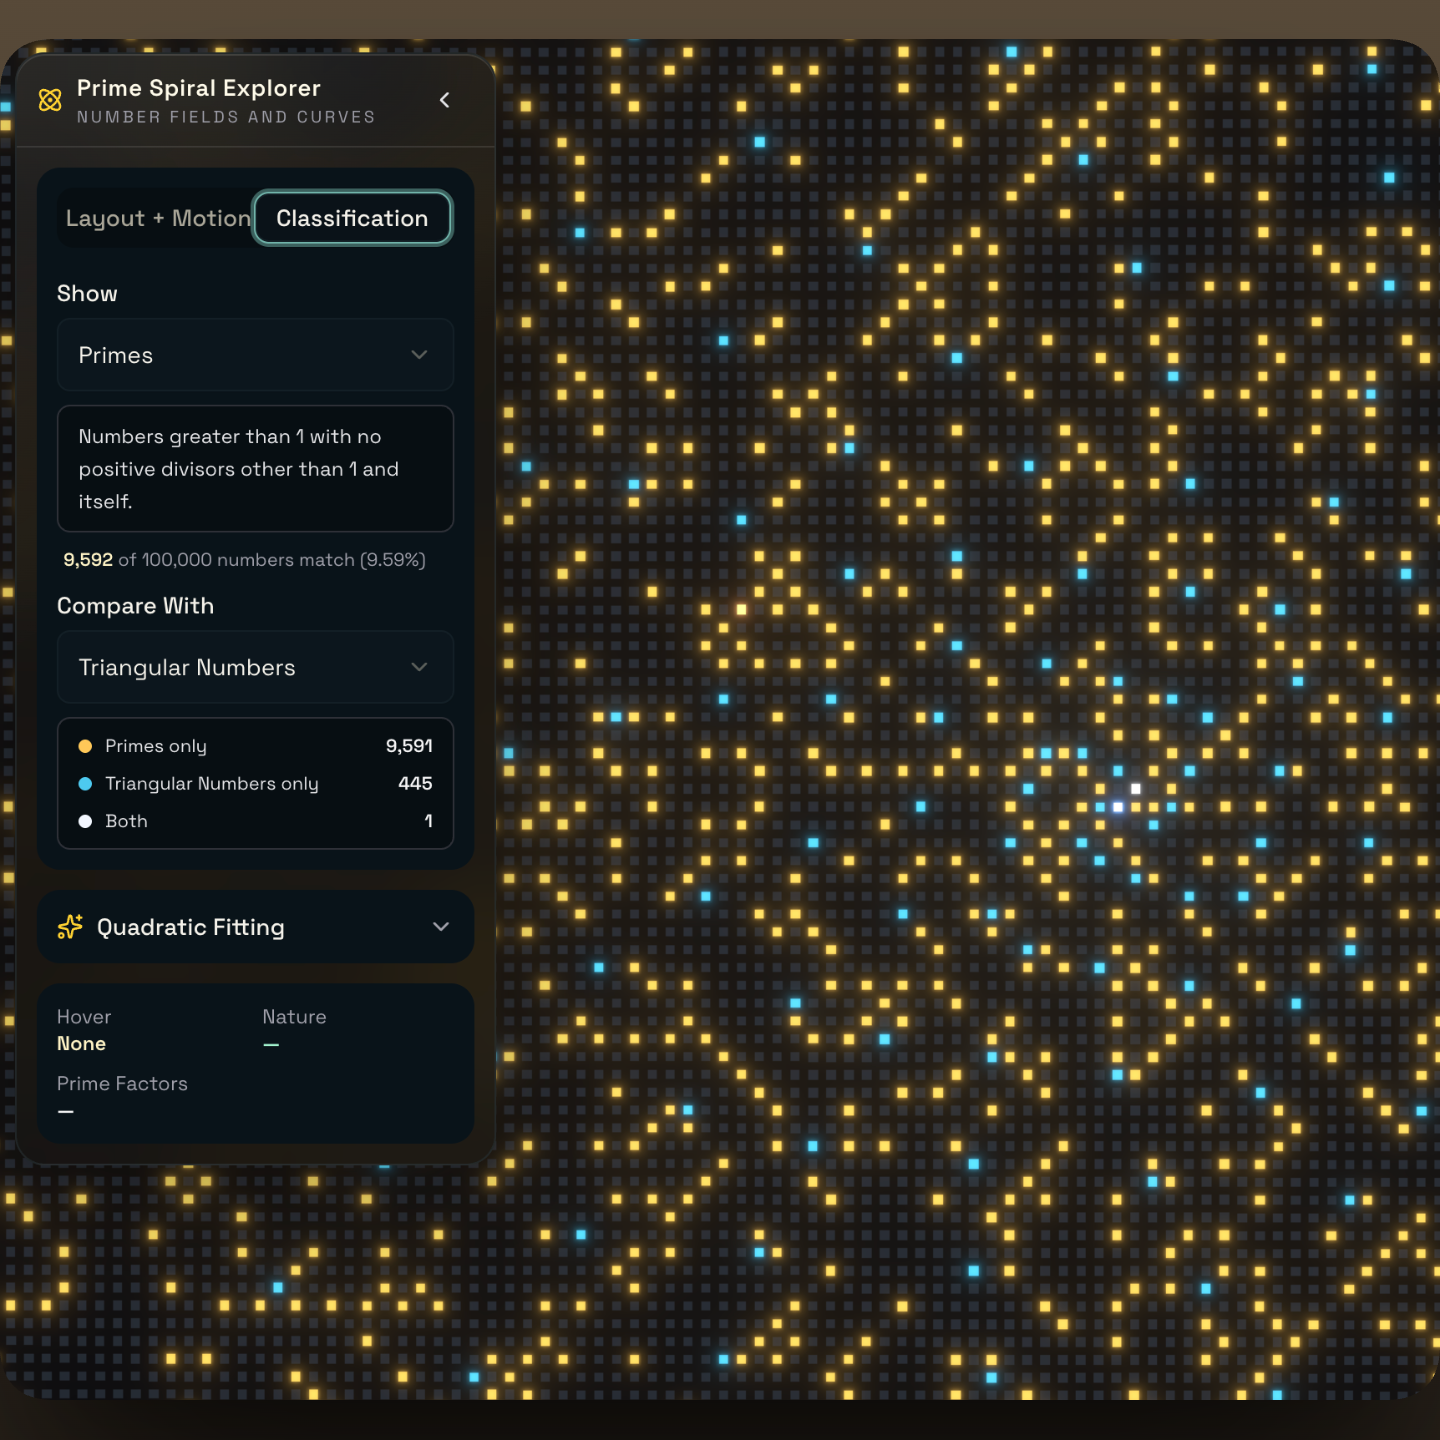
An interactive playground for seeing number theory: 100,000 integers laid out on spiral grids, with classifications, comparisons, and curve-fitting overlays that turn famous theorems into things you…
Fractal Explorer: Deep Zoom in the Browser
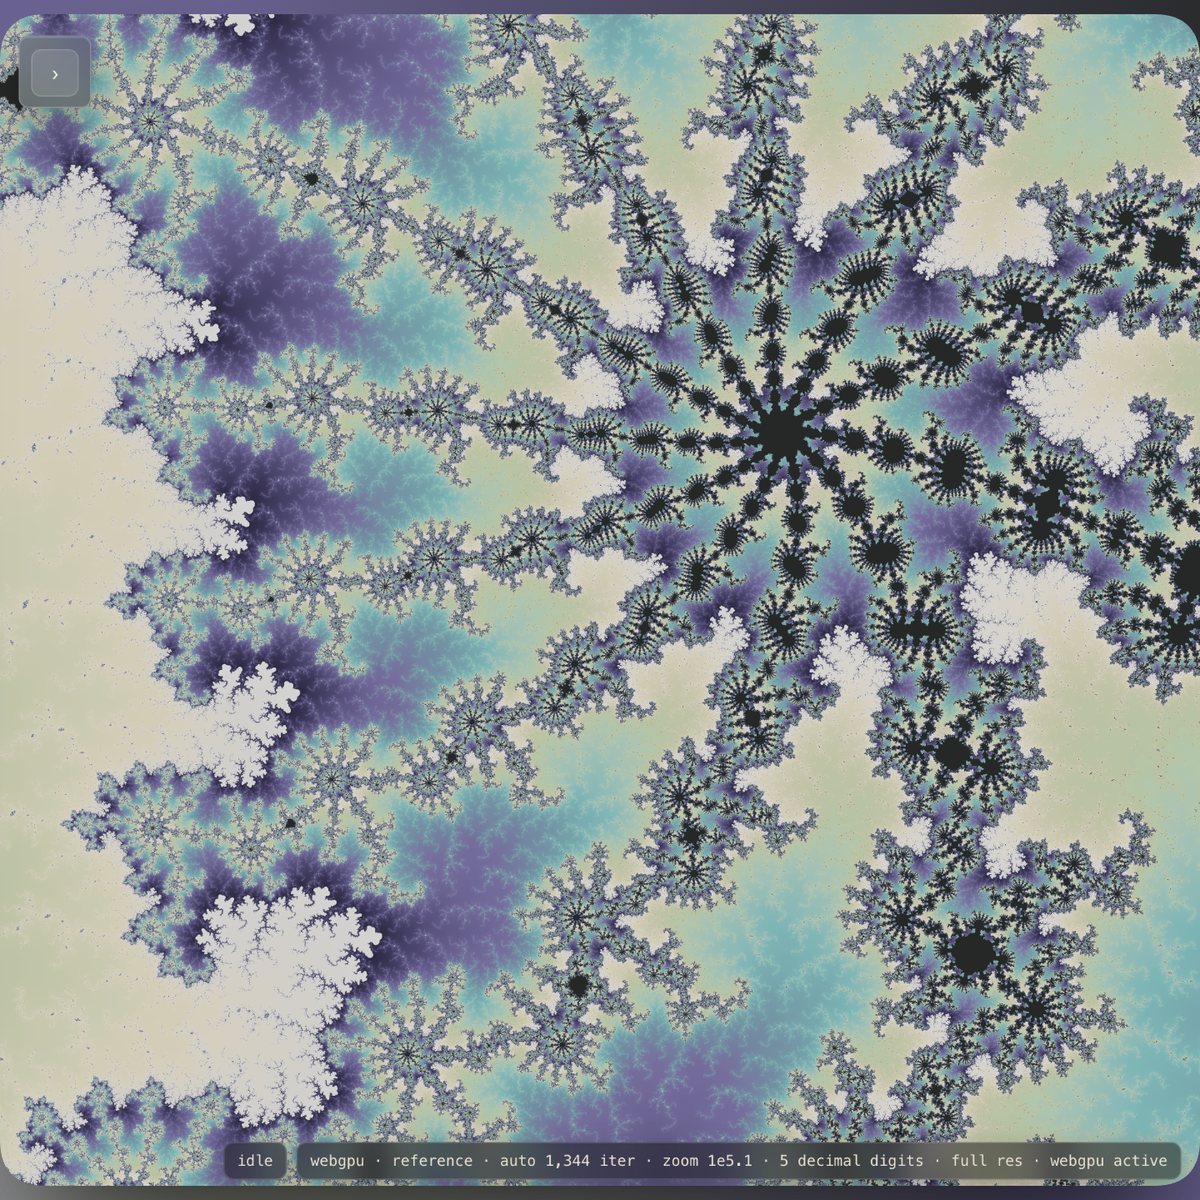
A single-page WebGPU app for exploring escape-time fractals as an instrument rather than a renderer: pan, zoom, switch formulas, and remix colors while the image stays live, all the way down to zooms…
2025
Understanding Cohen’s Kappa
Your LLM judge and a human reviewer label the same 100 responses as Pass or Fail. They agree on 90. A 90% match rate sounds like the validation can end early.
Understanding Krippendorff’s Alpha
You’re building an LLM evaluation pipeline. Four contractors rate 500 model responses as “Good,” “Okay,” or “Bad.” The dashboard shows 87% pairwise agreement, comfortably above the bar your team set…
2023
generative future history
Let’s peer into the future encoded in an AI’s training data. With a bit of prompting, we can bootstrap a journey from today to next year to decades to millenia in the “future” – as a powerful LLM…
infinite storyteller
“Infinite Storyteller” is a generative choose-your-own-adventure, told with state-of-the-art speech synthesis, generative imagery, and presented as a Twitch broadcast in a real-time, 3d game engine.

